How to Design a Webhook Reconciliation Process for Custom Business Software Integrations
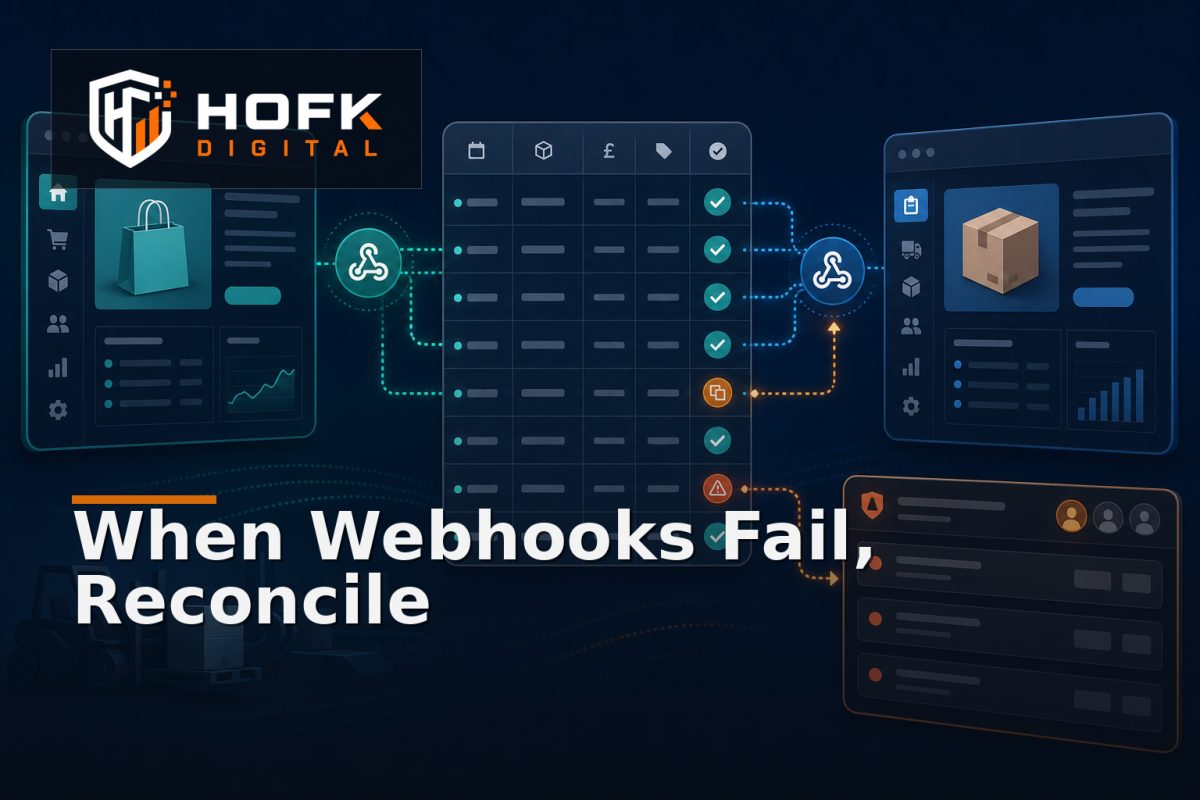
A webhook can return a successful HTTP response while the business process is still incomplete. An order update may be accepted but not applied, a payment event may be delivered twice, or a stock change may never arrive after a temporary provider outage.
That is why a webhook reconciliation process should be designed alongside the webhook handler itself. Delivery logs and retry settings are useful, but they do not prove that two connected systems eventually agree about the same customer, order, payment or operational state.
This guide explains how UK technical leads can design reconciliation for custom software integrations. It focuses on durable event records, idempotency, comparison jobs, replay controls and clear ownership when an integration event needs investigation.
Why webhook delivery is not the same as business completion
A webhook normally tells one system that something happened in another system. It may contain an event ID, an object reference and a payload. The receiving application then validates, stores and processes that message.
Several things can go wrong after the sender makes the request:
- The receiver is temporarily unavailable.
- The request times out after the sender has accepted it.
- The same event is delivered more than once.
- Events arrive in a different order from the business actions.
- The payload is accepted but a background job fails later.
- The receiving record has been deleted, changed or merged.
For example, a payment provider may deliver a payment-confirmed event, but the order application may fail before changing the order from pending to paid. From the provider's perspective, delivery may have succeeded. From the merchant's perspective, the order is still unresolved.
A reconciliation process exists to identify that difference rather than assuming that a successful request completed the whole workflow.
Define what integration event reconciliation must prove
Before choosing a queue, database table or monitoring tool, define the business questions the process needs to answer. A useful reconciliation design should help you establish:
- Was the expected event created by the source system?
- Did the receiving system accept and store it?
- Was the event processed exactly once from a business perspective?
- Did it produce the expected state change?
- Do both systems now agree about the relevant record?
- If they disagree, who owns the next action?
The answer will differ by integration. An order synchronisation may compare order status, totals and line items. A CRM integration may compare lead ownership, source data and qualification state. A stock integration may compare SKU, quantity, availability and update time.
Do not try to reconcile every field automatically at first. Start with the values that affect trading, customer communication, fulfilment or operational decisions.
Build an event ledger before building reports
The centre of a reliable webhook reconciliation process is usually an append-only event ledger. This is a durable record of what arrived, when it arrived and what the application did with it.
An event ledger does not need to replace your application database or accounting system. It provides an integration audit layer between the external message and the business result.
Useful fields may include:
- Internal event record ID.
- Provider or source-system event ID.
- Event type and schema version.
- Source system and destination system.
- Business object type and reference.
- Received timestamp and processing timestamps.
- Signature or authentication result.
- Payload location or safely stored payload reference.
- Processing status and failure reason.
- Retry count, replay status and owner.
Keep the original event separate from the current processing result. If a handler is corrected later, the history should still show what arrived originally and what happened during each attempt.
Retention, access and personal-data handling should be reviewed against your current systems and policies. VERIFY the appropriate retention period, redaction approach and access controls before storing full webhook payloads.
Design webhook failure handling around business impact
Not every failed webhook needs the same response. A low-priority marketing update can follow a different route from an event that releases stock, confirms payment or triggers fulfilment.
A practical severity model could include:
Critical integration failure
The event affects payment, order creation, stock accuracy, customer access or another core operational process. Escalate promptly and consider a controlled pause or fallback.
Recoverable processing failure
The event is stored, but processing failed because of a temporary API outage, timeout or unavailable dependency. Retry using a defined backoff schedule.
Data or business-rule exception
The message is valid technically but cannot be applied because a product, customer or order reference is missing, duplicated or inconsistent. Route it to an exception queue rather than retrying indefinitely.
Non-blocking discrepancy
The systems differ in a low-impact field or expected timing window. Record it for review without interrupting normal processing.
The exact thresholds should reflect your application, providers and operational risk. VERIFY response targets and escalation arrangements against your support coverage and supplier contracts.
Make handlers idempotent before adding replay
Replay is only safe when the receiving operation can tolerate the same event more than once. This is the practical connection between webhook failure handling and idempotency.
Use the source event ID, or another stable idempotency key, to prevent the same business action being applied twice. Store whether the event has been received, processed, failed or deliberately ignored.
Useful safeguards include:
- Unique database constraints on provider event IDs.
- Separate records for event receipt and business action.
- State-transition checks before applying an update.
- Upserts where they are appropriate.
- Provider request IDs stored for investigation.
- Replay operations that create a new attempt without hiding the original.
Do not rely only on a queue's duplicate-prevention feature. A queue may stop two jobs running at exactly the same time, but it does not necessarily prevent a later replay, manual retry or duplicate provider request from applying the same commercial change twice.
Reconcile expected events with actual events
A strong process compares more than failed webhook deliveries. It compares what should have happened with what the receiving system can prove happened.
For example, your reconciliation job might identify:
- Orders created in the source system with no matching event in the ledger.
- Events received with no resulting order-state transition.
- Payments marked complete by the provider but pending internally.
- Events processed more than once without a valid business reason.
- Records updated in one system but not reflected in another within the agreed window.
This may require an API pull, a report export, a database query or a provider-side event list. The important principle is to compare identifiers and business states, not just record counts.
Use a scheduled reconciliation job rather than relying on someone to notice a mismatch in a dashboard. The job should create an actionable exception with the source reference, affected business record, last known state and suggested next step.
Handle event ordering explicitly
Webhooks may arrive out of order. An order-created event can arrive after an order-paid event, or a customer update can arrive after a later correction. If the handler assumes perfect sequence, the final state may be wrong even though every event was delivered.
Where possible, use provider timestamps, sequence numbers or version values to decide whether an incoming event is newer than the state already applied. Store the event order and make transitions conditional.
Do not automatically apply an older event over a newer business state. If ordering cannot be established safely, send the event to review or request the current record from the source system.
Create a controlled replay and repair process
A reconciliation alert is only useful if the team can repair the issue safely. Define what an operator or technical lead is allowed to do from the exception queue.
Possible actions include:
- Retry the original processing attempt.
- Fetch the current source record and rebuild the missing update.
- Replay the event after correcting a known mapping issue.
- Mark the event as intentionally ignored with a reason.
- Escalate a business-rule conflict for manual decision.
Every replay should record who initiated it, why it was needed, what result followed and whether the event created a new external request. Avoid a single “retry all” button for important integrations.
For higher-risk actions, require a second approval or a dry-run comparison before applying the repair. VERIFY the appropriate approval level with your operational and finance owners where a replay could affect money, stock or customer commitments.
Monitor reconciliation health, not just queue health
A worker can be running while the integration is still unhealthy. Monitor the signals that show whether the business outcome is keeping up with the event flow.
Useful measures include:
- Unprocessed events by age and severity.
- Events failing after all retry attempts.
- Duplicate event rate.
- Events without a matching business record.
- Business records without an expected event.
- Time from event receipt to confirmed state change.
- Manual replays and recurring exception types.
Alerts should identify what decision is needed. “Webhook failed” is less useful than “14 paid orders remain pending internally for more than 10 minutes; payment-provider references attached; operations owner assigned”.
Test the reconciliation process before go-live
Include controlled failures in the test plan. A clean delivery test proves very little on its own.
Test at least:
- Provider sends the same event twice.
- Receiver times out after the source accepts the request.
- Event arrives before its related record exists.
- Events arrive out of order.
- Background processing fails after the event is stored.
- A replay is attempted after a manual correction.
- The source and destination contain conflicting values.
- The provider changes its payload version or adds a required field.
For each scenario, compare the event ledger, application state, provider record and operator-facing exception. A successful test should prove not only that the system recovers, but that the recovery is visible and does not create a harmful duplicate.
Webhook reconciliation process checklist
- Critical integration outcomes are defined in business terms.
- Incoming events are stored in a durable ledger.
- Event IDs and business references are stable and searchable.
- Handlers are idempotent and safe to retry.
- Out-of-order events have an explicit treatment.
- Reconciliation compares source and destination states.
- Exceptions have severity, ownership and next actions.
- Replay and repair actions are controlled and audited.
- Monitoring covers event age, failure, duplication and mismatch.
- Failure scenarios have been tested before launch.
Where HOFK can help
Webhook-driven integrations often connect ecommerce platforms, CRMs, ERPs, payment providers, fulfilment tools and internal operational applications. HOFK can help map those handoffs, improve full stack implementation, add practical monitoring or build an exception and reconciliation workflow around the systems you already use.
Relevant support may include full stack development, ecommerce, automation and website monitoring. The objective is not to add more events for their own sake. It is to make the important business state easier to verify, repair and explain.
Conclusion
A dependable webhook reconciliation process does more than retry failed requests. It records incoming events, prevents harmful duplicates, compares expected and actual states, handles event ordering and gives the team a controlled way to repair exceptions.
Start with one critical integration. Define the business outcome, create an event ledger, make the handler idempotent and add a scheduled comparison between the source and destination systems. Then test duplicate delivery, delayed processing, out-of-order events and manual replay before trusting the integration in live operations.
That approach makes integration event reconciliation a practical control rather than a technical afterthought. If your custom software integrations still depend on inboxes, undocumented retries or manual database checks, HOFK can help review the handoffs and build a more maintainable route from webhook receipt to confirmed business outcome.
Frequently asked questions
What is a webhook reconciliation process?
It is a structured way to compare webhook events, processing results and business records so missed, duplicated or incorrectly applied updates can be identified and repaired.
Why are webhook retries not enough?
Retries may deliver a message again, but they do not prove that the receiving application applied the correct business state. Reconciliation checks the result as well as delivery.
How can webhook failure handling prevent duplicate updates?
Use stable event IDs, unique constraints, idempotent handlers and state-transition checks before applying an event more than once.
What should an event reconciliation queue contain?
It should show the source event, affected business record, failure or mismatch reason, severity, owner, next action and replay or resolution history.
When should a webhook be replayed?
Replay it only when the handler is safe to run again and the cause of the original failure is understood. Record the replay and its result rather than treating it as a hidden retry.