How to Plan Retained Development Capacity for Emergencies and Improvements
A retained development arrangement can give your business continuity, technical context and a reliable route for improving a website or application. However, the capacity can disappear quickly when urgent issues arrive, a campaign deadline moves forward or several teams request work at the same time.
Without an agreed allocation model, planned improvements are repeatedly pushed aside while emergency tasks consume the month. Alternatively, a team may reserve too much unused time for incidents and make little progress on the development backlog.
This is the practical challenge behind retained development capacity planning: how to protect enough time for urgent support while still delivering meaningful, planned improvements.
This guide is for UK founders, digital leads, ecommerce managers and operations teams using a development support retainer. It explains how to divide capacity, schedule work, handle unused emergency time and review whether the arrangement is producing the right balance of responsiveness and progress.
What retained development capacity planning should achieve
Capacity planning should make the retainer easier to use and easier to manage. It should help answer four questions:
- How much capacity is available during the period?
- How much should be protected for urgent incidents?
- Which planned improvements are most important?
- What happens when emergency demand is higher or lower than expected?
The aim is not to predict every request perfectly. It is to create a reasonable operating model that makes trade-offs visible before the team is under pressure.
A useful plan should also distinguish between different types of work. A payment failure, a routine dependency update, a landing-page improvement and a new internal workflow should not automatically compete in one undifferentiated queue.
Separate the main types of retainer capacity
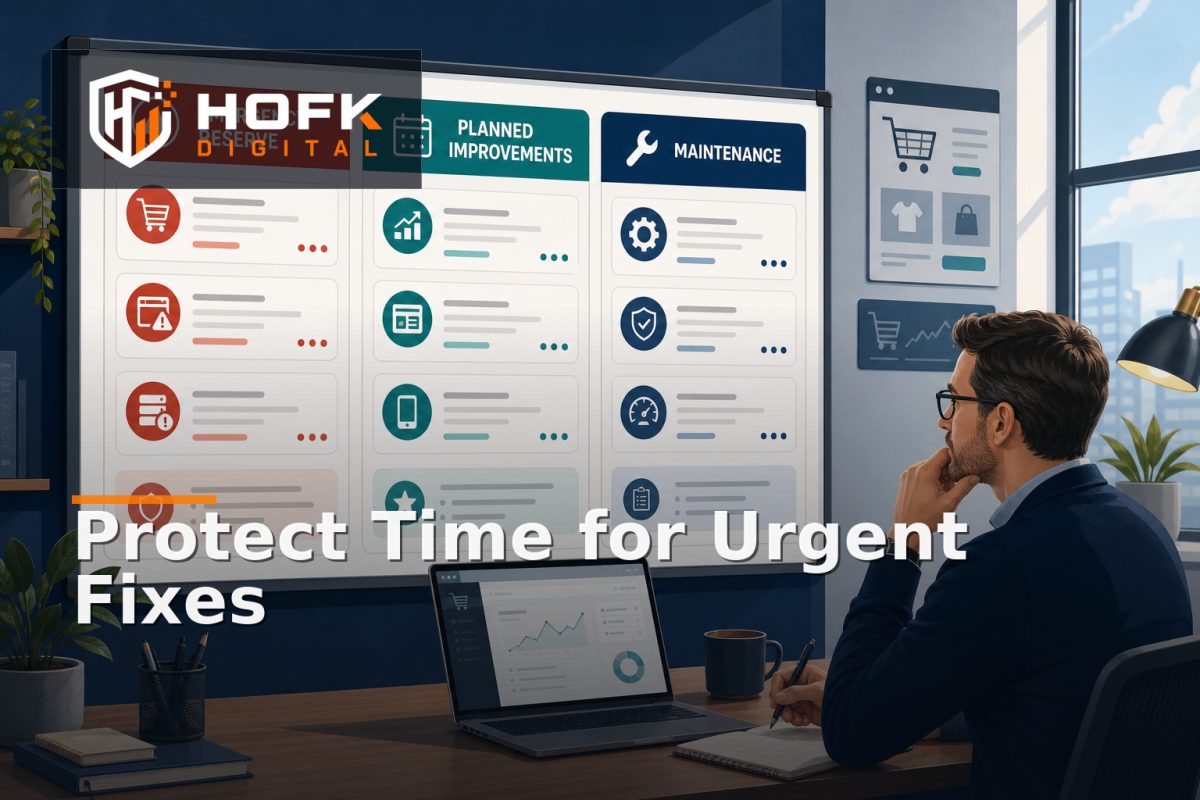
A simple capacity model normally works better when the available time is divided into clear allocations. The exact proportions should reflect the website, application, trading cycle and support agreement, but four categories are a useful starting point.
1. Emergency and incident reserve
This is protected capacity for issues that need a prompt response because they affect trading, customers, data, operational continuity or a critical integration.
Examples might include:
- Checkout or payment failures
- Lead forms not reaching the CRM or inbox
- Incorrect customer-specific pricing
- Broken stock, fulfilment or order handoffs
- Serious security or availability concerns
Reserve time is not a guarantee that every issue will be resolved immediately. The response depends on the support agreement, access, third-party providers and the nature of the failure. It does create a deliberate buffer so an urgent issue does not automatically consume every planned improvement.
2. Planned improvement capacity
This is the time used for agreed work that improves the website, application or operating process. It might include a checkout improvement, a new ecommerce workflow, a responsive template change, an integration enhancement or a focused automation task.
Planned capacity should be attached to outcomes rather than a list of loosely described tickets. For example, “reduce manual order corrections by improving the exception workflow” is more useful than “update order admin”.
3. Maintenance and risk reduction
Maintenance work protects the future reliability of the system. It may include application dependency updates, monitoring improvements, technical debt reduction, backup checks, performance work or changes needed to keep an integration supportable.
This work can be difficult to justify when there is no visible customer-facing feature. However, leaving no capacity for maintenance means known risks compete with urgent incidents later, often at a higher cost.
HOFK’s guide to building a software maintenance plan provides related guidance on dependencies, risk levels and release windows.
4. Planning, review and communication
A small amount of time is needed to review priorities, clarify requirements, assess completed work and agree the next delivery sequence. This should not become unnecessary administration, but it should be recognised as part of a healthy retainer.
If planning time is ignored, requests often arrive incomplete, work starts before the outcome is understood and capacity reports become difficult to interpret.
Choose an allocation model that suits the risk
There is no universal percentage split for every retainer. A high-volume ecommerce operation may need a larger incident reserve than a brochure website. An application with several external integrations may need more maintenance capacity than a relatively stable marketing site.
Three practical models are worth considering.
Fixed reserve
A fixed portion of each month is reserved for emergencies. If it is not used by an agreed review point, the business decides whether it can be released into planned improvements.
This model is easy to understand and works well when support demand is relatively predictable.
Rolling reserve
Unused emergency capacity carries forward for a defined period, subject to an agreed limit. This can help where incidents are infrequent but occasionally require more time than one month provides.
Set a maximum balance so the reserve does not become an unclear accumulation of unused hours.
Priority-based flex capacity
The reserve changes according to known risk. For example, more capacity may be protected before a major campaign, migration, seasonal trading period or significant integration release.
This model is more responsive, but it requires better communication and forward planning. The business should agree when the reserve changes and who can approve the adjustment.
VERIFY: the appropriate reserve model should be agreed with the development partner and reviewed against the support contract, release frequency, trading calendar and operational risk.
Reserve capacity before the month starts
Capacity planning works best before requests begin competing for time. At the start of each period, review:
- The total retained capacity available
- Expected support coverage and working days
- Known campaigns, launches or migrations
- Planned platform or dependency changes
- Outstanding incidents and technical risks
- High-priority items in the development backlog
Then create a provisional allocation. It does not need to be exact. Its purpose is to show how much capacity is already committed, how much is protected and which improvements can realistically fit.
For example, an illustrative retainer might reserve capacity for urgent support, planned improvements, maintenance and review. The exact split should not be copied from another business. It should reflect the evidence from your own support history.
Use development backlog scheduling to protect progress
A backlog becomes more useful when it has a delivery horizon. Instead of treating every approved item as equally ready, group work into:
- Ready: requirements, access and acceptance criteria are sufficiently clear.
- Next: likely to be scheduled in the next capacity window.
- Later: worthwhile, but not yet ahead of higher-priority work.
- Blocked: waiting for information, approval, supplier action or another dependency.
This is the practical side of development backlog scheduling. It prevents the team from promising a long list of work that cannot all fit into the available capacity.
HOFK’s article on prioritising a website support retainer backlog covers risk, commercial value, urgency, confidence and effort. Capacity planning adds another question: even if an item is important, when can it realistically fit?
Set rules for using the emergency reserve
An emergency reserve needs clear entry criteria. Otherwise, every urgent-sounding request may consume protected time.
Before using the reserve, record:
- The affected customer, trading or operational journey
- The impact and scope of the issue
- When it was first detected
- The immediate mitigation or workaround
- The person responsible for the next decision
A useful severity model might distinguish between critical incidents, high-impact degradation, standard defects and planned requests. The precise labels are less important than the action attached to each level.
HOFK’s guide to setting a website support SLA around business impact provides related principles for separating acknowledgement, investigation, workaround and resolution.
Decide what happens when reserve time is unused
Unused emergency capacity should not disappear without explanation, but it should not automatically become a promise of extra development either.
Agree one of the following approaches:
- Release unused time into a planned improvement before the next review point
- Carry a limited amount into the following period
- Use it for an agreed maintenance or technical-risk task
- Keep it available because an upcoming event increases operational risk
Document the decision. This helps avoid the assumption that unused reserve is automatically available for any new request. It also makes the commercial value of the retainer easier to understand.
Protect planned work when incidents occur
When an emergency uses capacity, do not silently remove planned work from the schedule. Reassess the plan and make the consequence visible.
There are several possible responses:
- Defer a lower-priority improvement
- Reduce the scope of an improvement while protecting its core outcome
- Move work into the next period
- Approve additional capacity if the work is commercially urgent
- Pause a planned task because the incident revealed a deeper risk
The important point is to record why the change happened. This prevents the development team from appearing unreliable when the real issue was a legitimate priority shift.
Measure whether the capacity model is working
Review the retainer at regular intervals using a small number of useful measures. Avoid judging the arrangement only by tickets closed.
Consider tracking:
- Capacity used for incidents, maintenance and planned improvements
- Emergency reserve used and released
- Planned work carried forward and why
- Repeat incidents or recurring defects
- Time spent waiting for approvals or information
- Improvements delivered against their agreed outcome
HOFK’s guide to retained development reporting beyond tickets closed explains how to connect activity with outcomes, reliability and efficiency.
Retained development capacity planning checklist
Before starting the next planning period, confirm that:
- Total available capacity is understood.
- Emergency reserve has a named purpose and owner.
- Planned improvement capacity is protected where possible.
- Maintenance and risk reduction have not been forgotten.
- Backlog items have clear horizons and acceptance criteria.
- Emergency entry criteria are documented.
- Unused reserve has an agreed treatment.
- Incident impact on planned work is recorded.
- Upcoming campaigns, releases and trading risks are visible.
- The next review date is agreed.
Where HOFK can help
HOFK supports businesses with retained development, ecommerce, responsive websites, SEO and Google Ads, automation and website monitoring. That combination is useful when capacity decisions cross customer journeys, integrations, operational tools and marketing activity.
Support may include reviewing the backlog, defining capacity categories, improving monitoring, scheduling software improvements or delivering full stack work within a clearer support model. The objective is not to consume every available hour. It is to make development capacity easier to protect, explain and use commercially.
Conclusion
Retained development capacity planning works best when it separates emergency reserve from planned improvements, maintenance and review. Set the allocation before the period starts, define when reserve time can be used, schedule the backlog against realistic capacity and make the impact of incidents visible.
A good website support retainer should provide both responsiveness and progress. It should help your team handle an urgent checkout or integration problem without abandoning every important improvement. With clear rules and regular review, retained development becomes a more dependable operating model rather than an informal queue of requests.
Frequently asked questions
What is retained development capacity planning?
It is the process of dividing development support capacity between emergency response, planned improvements, maintenance and review so priorities remain clear.
How much retainer capacity should be reserved for emergencies?
There is no universal percentage. The reserve should reflect incident history, trading risk, integrations, support coverage and the business calendar. VERIFY the right level against your support arrangement.
What happens if emergency capacity is not used?
Agree whether unused time is released into planned improvements, carried forward within a limit, used for maintenance or retained for an upcoming high-risk period.
How can planned improvements survive urgent support work?
Protect a planned-work allocation, define emergency entry criteria and record which tasks are deferred when an incident consumes capacity.
How should a website support retainer be measured?
Review capacity used for incidents, maintenance and improvements, along with repeat defects, carried-forward work, waiting time and the outcomes delivered.