How to Use SEO Log File Analysis to Find Crawl Waste on Large Websites
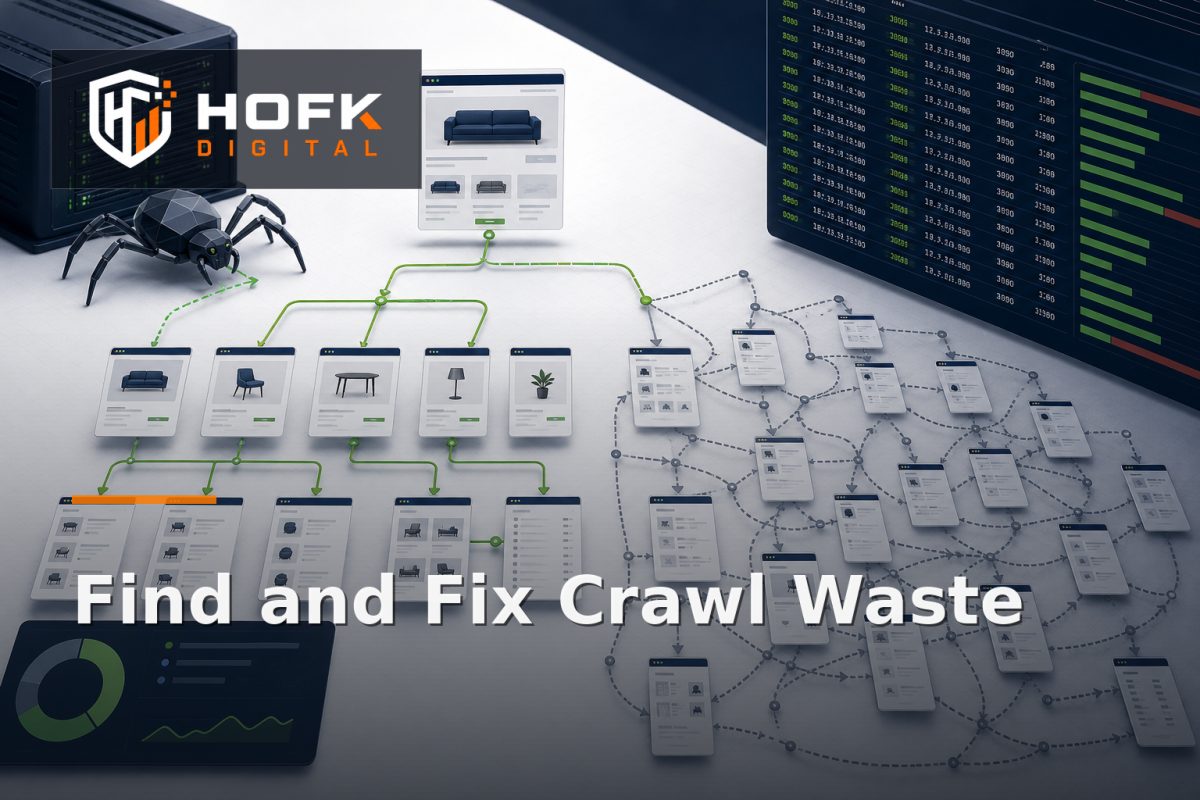
A large website can have thousands or millions of URLs, but search engine bots do not crawl every URL equally. They may spend time on old parameters, duplicate filter combinations, internal search results, tracking URLs, expired products or repeatedly redirected pages while important content receives comparatively little attention.
This is where SEO log file analysis becomes useful. Instead of inferring crawler behaviour from crawl tools, server reports or indexed URLs alone, you examine the requests that search engine bots actually made to your server. That evidence can show where Googlebot, Bingbot and other crawlers are spending time, which URL patterns create waste and whether technical changes are improving the crawl path.
This guide explains how UK SEO managers and technical teams can use search engine bot logs to perform crawl budget analysis, identify technical SEO crawl waste and prioritise fixes on large or complex websites.
What SEO log file analysis can reveal
Server logs record requests made to your website, normally including the requested URL, timestamp, response status, user agent, referrer and sometimes response time or cache information. When filtered for verified search engine crawlers, those records provide a practical view of crawl behaviour.
Log analysis can help you identify:
- Important pages that search engine bots rarely request.
- Large volumes of crawling on parameter or filter URLs.
- Repeated requests for redirects, errors or soft-deleted content.
- Internal search pages being crawled unnecessarily.
- Bot activity concentrated on duplicate or near-duplicate templates.
- Slow responses affecting crawl efficiency.
- Changes in crawl behaviour after a release, migration or catalogue import.
It does not replace crawling tools, Search Console or an XML sitemap review. It answers a different question: what did search engine bots request from the server during the period analysed?
Start with reliable search engine bot logs
The quality of the analysis depends on the quality of the log source. Ask your hosting, infrastructure or development team which logs are available and how long they are retained. Common sources include web server access logs, CDN logs, load balancer logs and cloud infrastructure logs.
For each request, try to retain:
- Timestamp, including timezone.
- Requested URL and query string.
- HTTP method.
- Response status code.
- User agent.
- IP address or an anonymised identifier.
- Response time or upstream timing where available.
- Host and protocol.
Do not assume that a user agent containing “Googlebot” is genuine. For dependable analysis, verify important crawler traffic using the relevant reverse-DNS and forward-DNS process, or use an established verification method supported by your technical team. VERIFY the current verification procedure before publishing or implementing an automated rule.
Choose an analysis period that reflects the website
A single day may be too volatile for a large ecommerce site. A full year may create too much data and hide recent changes. Start with a period that reflects the website’s crawl frequency, release cycle and trading pattern.
A practical starting point is:
- Seven days for an initial technical snapshot.
- Twenty-eight to thirty days for a more representative crawl budget analysis.
- A before-and-after comparison around a migration, release or major SEO change.
Record the period, environment and filters used. If the website has separate domains, subdomains, regional stores or mobile applications, decide whether they should be analysed together or separately.
Group URLs by pattern before reviewing individual pages
Large websites create too many URLs for manual review. Begin by grouping requests into patterns that represent how the site works. This is usually more useful than sorting a spreadsheet by individual URL.
Useful groups may include:
- Product, service and category pages.
- Pagination URLs.
- Faceted navigation and filter combinations.
- Sort and view parameters.
- Internal search results.
- Tracking parameters such as campaign or session values.
- Login, account, basket and checkout routes.
- Redirected, missing or retired URLs.
- Feeds, APIs, image paths and other non-HTML resources.
Normalise query strings carefully. Some parameters change the page meaningfully, while others create duplicate URLs without changing the visible content. Keep the original URL available so technical teams can investigate individual examples later.
Find the main types of technical SEO crawl waste
Parameter and tracking URLs
Campaign parameters, sorting options, session identifiers and other query strings can create many crawlable variations. If internal links or external references expose those URLs, bots may continue requesting them even when they offer no independent search value.
Measure both the number of requests and the proportion of bot activity they represent. A parameter pattern generating a few requests may not matter. A pattern receiving thousands of requests each day deserves investigation.
Faceted navigation combinations
Filters can create valuable customer journeys, but most combinations are not useful search pages. Bots may crawl combinations with very little stock, repeated content or no meaningful demand. Compare filtered URL requests with product count, indexation intent and internal-link exposure.
HOFK’s guide to building an ecommerce faceted navigation SEO plan covers the wider process of deciding which filtered pages should be indexable, controlled or treated as user-only states.
Redirects and error responses
Requests returning 3xx, 4xx or 5xx responses deserve their own view. A few old redirects are normal, especially after a migration. A large volume of repeated redirects can indicate redirect chains, stale internal links or external links pointing to outdated URLs.
Repeated 404 requests may identify broken internal references, old feed URLs or links that should be redirected. Repeated 5xx responses are more urgent because they may prevent bots and users from accessing important content.
Internal search and low-value utility pages
Internal search results, account routes, cart URLs and other utility pages may appear in logs even when they are not intended for organic search. Check whether these URLs are linked, crawlable and returning appropriate signals. Do not assume that a robots.txt rule alone resolves every indexation or discovery issue. VERIFY the correct technical treatment against the current platform and search documentation.
Slow responses
If response timing is available, group bot requests by URL pattern and response duration. A slow category or product template may consume more server resources and reduce the number of useful requests that can be handled during busy periods.
Response time alone does not prove a crawl problem. Compare it with traffic, caching, server capacity and customer impact. A slow endpoint used only by an internal tool is different from a slow template requested thousands of times by crawlers and shoppers.
Compare bot activity with your priority URL set
Do not judge crawl efficiency only by the total number of requests. Compare bot activity with the pages the business wants search engines to understand and revisit.
Create a priority set containing:
- Important category and collection pages.
- High-margin or strategically important products.
- Core service or location pages.
- New or recently updated content.
- Pages receiving organic traffic or valuable links.
Then ask:
- Are priority pages being crawled at a reasonable frequency?
- Are bots spending more time on low-value URL groups?
- Do recently updated pages receive visits after publication?
- Are important pages returning successful, fast responses?
Be careful with the phrase “crawl budget”. Google’s crawling behaviour depends on many factors, including site size, server capacity, content quality and perceived demand. Treat the log as evidence for prioritisation rather than a promise that one technical change will produce a fixed crawl increase.
Prioritise fixes by waste and business impact
A large URL group is not automatically the first problem to fix. Prioritise using both crawl waste and commercial or technical impact.
A useful prioritisation model considers:
- Volume: How many verified bot requests are involved?
- Value: Are important pages, products or categories affected?
- Waste: Does the pattern create duplicates, redirects, errors or thin pages?
- Confidence: Is the cause supported by logs, crawling and site data?
- Fix risk: Could the proposed change affect users, paid traffic or valid discovery?
For example, reducing low-value parameter crawling may be worthwhile, but not if the rule accidentally blocks useful product URLs. A safer first fix may be to remove unnecessary internal links, correct canonical signals or prevent the platform from generating the URLs in the first place.
Validate changes with a before-and-after comparison
Log analysis becomes more valuable when it is part of a controlled improvement cycle. Before making a change, record the baseline for the affected URL group. After deployment, compare the same metrics over a similar period.
Review:
- Total verified bot requests by URL group.
- Successful, redirected and error responses.
- Requests to priority pages.
- Requests to parameters, filters and utility URLs.
- Response time for important templates.
- Changes in crawl patterns after releases.
Do not expect every request to disappear immediately. Crawlers may retain known URLs and revisit old patterns for some time. Look for a sustained change, not a single quiet day.
Build SEO log file analysis into release QA
Crawl waste can return after a template change, catalogue import or migration. Add log review to the release process for changes that affect URL generation, navigation, filters, redirects, canonicals or internal search.
HOFK’s guide to adding visual regression checks to a website release process covers a different type of release control, but the principle is similar: define important checks, assign ownership and review unexpected changes rather than accepting them as normal.
A practical release check can include:
- Record the URL patterns affected by the change.
- Confirm the intended canonical, robots and linking behaviour.
- Test representative pages and filter states.
- Monitor bot requests after deployment.
- Review new redirects, errors and unexpected parameters.
- Record any accepted differences and follow-up actions.
When log analysis needs technical implementation support
Log files can show that waste exists, but not always why the website generates it. The cause may sit in a CMS, ecommerce platform, search service, CDN rule, template, internal-link component or integration.
That is where HOFK’s full stack development and ecommerce support can be relevant. The useful work may involve tracing URL generation, improving filter handling, fixing redirect logic, changing a data model or adding monitoring around unusual crawl patterns. The objective is not to block bots broadly. It is to make the website easier for search engines to crawl without damaging customer journeys.
SEO log file analysis checklist
- Collect complete, timestamped server or CDN logs.
- Verify search engine bot traffic before drawing conclusions.
- Choose an analysis period that reflects the site and release cycle.
- Group URLs by templates, parameters and response types.
- Measure requests to redirects, errors, filters and utility pages.
- Compare bot activity with priority URLs and recently updated content.
- Prioritise fixes by crawl waste, business value and implementation risk.
- Record a baseline before making technical changes.
- Repeat the analysis after releases, migrations and URL-model changes.
Conclusion
SEO log file analysis gives large website teams evidence about what search engine bots actually request, rather than relying only on assumptions from crawlers, sitemaps or indexation reports. By grouping search engine bot logs into URL patterns, you can identify technical SEO crawl waste caused by parameters, filters, redirects, errors, utility pages and slow templates.
Use crawl budget analysis as a prioritisation exercise, not a target to chase blindly. Focus first on patterns that consume substantial crawl activity, affect important pages or expose a clear technical risk. Then validate the result with a before-and-after comparison and add log review to release QA.
If your website generates large numbers of filtered URLs, stale redirects or inconsistent crawl patterns, HOFK can help connect the SEO evidence with ecommerce, full stack development, monitoring and practical implementation work.
Frequently asked questions
What is SEO log file analysis?
SEO log file analysis is the review of server or CDN request logs to understand how verified search engine bots crawl a website, including which URLs they request and what responses they receive.
How does log analysis identify crawl waste?
It groups bot requests by URL pattern and highlights activity on parameters, filters, redirects, errors, utility pages or other URLs that do not provide proportionate search value.
Is crawl budget analysis only relevant to very large websites?
It is most valuable on large, complex or frequently changing websites, but smaller sites can still use logs to investigate repeated errors, redirect patterns or unexpected bot activity.
Can robots.txt alone prevent technical SEO crawl waste?
Not always. Crawl behaviour is influenced by links, URL discovery, canonical signals, redirects and platform behaviour. The correct treatment should be tested against the website and current search documentation.
How often should search engine bot logs be reviewed?
Review frequency should match website size and change rate. A monthly review is a practical starting point, with additional checks after migrations, URL changes, major catalogue updates or template releases.